Much of the information a business runs on still arrives as documents: invoices, delivery notes, contracts, forms. AI Optical Character Recognition, or OCR AI, turns scanned paper documents, PDFs and images into editable, searchable and structured data that systems can use.
In this article, we explain how AI OCR software works, where enterprises use it, what can go wrong and how to start.
What Is AI Optical Character Recognition (OCR AI)?
OCR AI is text recognition and data extraction done by trained neural networks instead of hand-written rules. It takes an image or scanned document and returns the text on it, its position on the page and, in modern systems, the specific fields a business needs, such as an invoice number or a delivery address.
Traditional OCR matched the shapes of individual characters against stored patterns and features. It worked on clean, printed pages in known fonts and broke on poor scans, unusual layouts and handwriting. Modern engines use deep learning: convolutional networks read the image, and sequence models (LSTMs, and increasingly transformers) recognize whole words and lines in context. The open-source Tesseract engine, for example, switched to an LSTM-based recognizer in version 4 (documentation). Because these models are trained on very large sets of printed and handwritten text, they cope with many fonts, layouts and languages without per-document configuration.
The biggest recent change is the arrival of vision-language models: AI models that look at a page image and read it the way a person does, understanding text, tables, stamps, checkboxes and handwriting in context. Instead of first converting a page into raw text and then writing rules to find the invoice number, you can ask such a model to return the fields you need, such as supplier, date, line items and totals, as structured data. Classic OCR engines are still used where speed and cost per page matter most, and many production systems combine both.
| Approach | What it returns | Strengths | Weak spots | Typical use |
|---|---|---|---|---|
| Classic OCR engine (e.g. Tesseract) | Raw text with positions | Fast, cheap, runs on your own servers | No understanding of fields; needs rules or templates per layout | Searchable archives, simple fixed forms |
| Document AI service with prebuilt models | Text plus predefined fields (invoice, receipt, ID) | Ready-made fields, confidence scores, mature APIs | Limited to the document types the vendor supports; custom types need training | High-volume invoices and receipts |
| Vision-language model with a schema | The fields you specify, as structured data | Handles new layouts and document types from instructions; reads tables and handwriting | Slower and costlier per page; can return a plausible value that is not on the page | Varied documents, long-tail suppliers, complex forms |
Many production pipelines route documents between these: a cheap engine or prebuilt model for the common formats, a vision-language model for the rest, and the same validation layer behind both.
This makes AI OCR especially useful for businesses that handle thousands of documents, like logistics enterprises. For instance, it extracts data from invoices, receipts, and contracts with varied formatting and styles, including layouts the system has never seen before. Accuracy is measured field by field, not page by page: a system can read 99% of characters correctly and still get the one field that matters, the total amount, wrong. That is why well-built AI OCR attaches a confidence score to every field and sends uncertain ones to a person for review.
Integrating OCR AI into workflows changes what people do with documents. Instead of typing every field, staff review the small share of fields the system is unsure about and handle the exceptions: a missing purchase order, a price that does not match the contract, an unreadable stamp. Mobile apps with AI OCR move the capture point to where the document is, such as a driver photographing a signed delivery note at the customer’s door, so the data reaches the system the same day instead of at the end of the week.
Why Is AI OCR Important for Modern Enterprises?
The main benefit is automation of data entry and information extraction, which makes operations faster. Manual data entry is slow and error-prone, and errors are expensive in logistics. AI OCR reduces manual work and shortens processing times.
In addition, AI OCR supports data integrity. A small mistake in one entry may later result in serious consequences for decisions and reports. AI-powered solutions reduce manual typing errors, and validation rules in code catch what the model gets wrong: line items must add up to the total, a VAT number must have a valid format, a purchase order number must exist in the ERP. This paves the way for reliable insights based on accurate Data Analytics services.
Another way to implement AI OCR technology is as a part of services carried out by business agents on the go. For example, in logistics this can be quick information entering and invoice processing using a smartphone camera. Meanwhile, OCR can be a part of a larger document workflow. We built an OCR solution for invoice processing for an international transportation and logistics company that tells invoices from CMR notes, extracts key fields, detects errors and validates seals, and an OCR retail receipt data extraction tool that processes receipts in five languages for consumer behavior analysis. Image analysis can also be one part of a more complex tool, like vehicle damage assessment for insurance companies.
AI OCR can also improve customer experience. Businesses that handle many customer documents, such as invoices or contracts, process them faster and can answer customers sooner.
Compliance is another reason. Regulations in many industries require documents to be processed and stored correctly. AI OCR helps by capturing documents consistently and keeping an audit trail of what was extracted, checked and changed, which makes compliance easier to demonstrate during inspections.
Uncover the Power of AI OCR
Use the Optical Character Recognition technology to automate processes, speed up data entry, and make working with documents much faster.
How Does AI OCR Work?
The next logical question after you learn ‘What is OCR software?’ is ‘How does it work?’
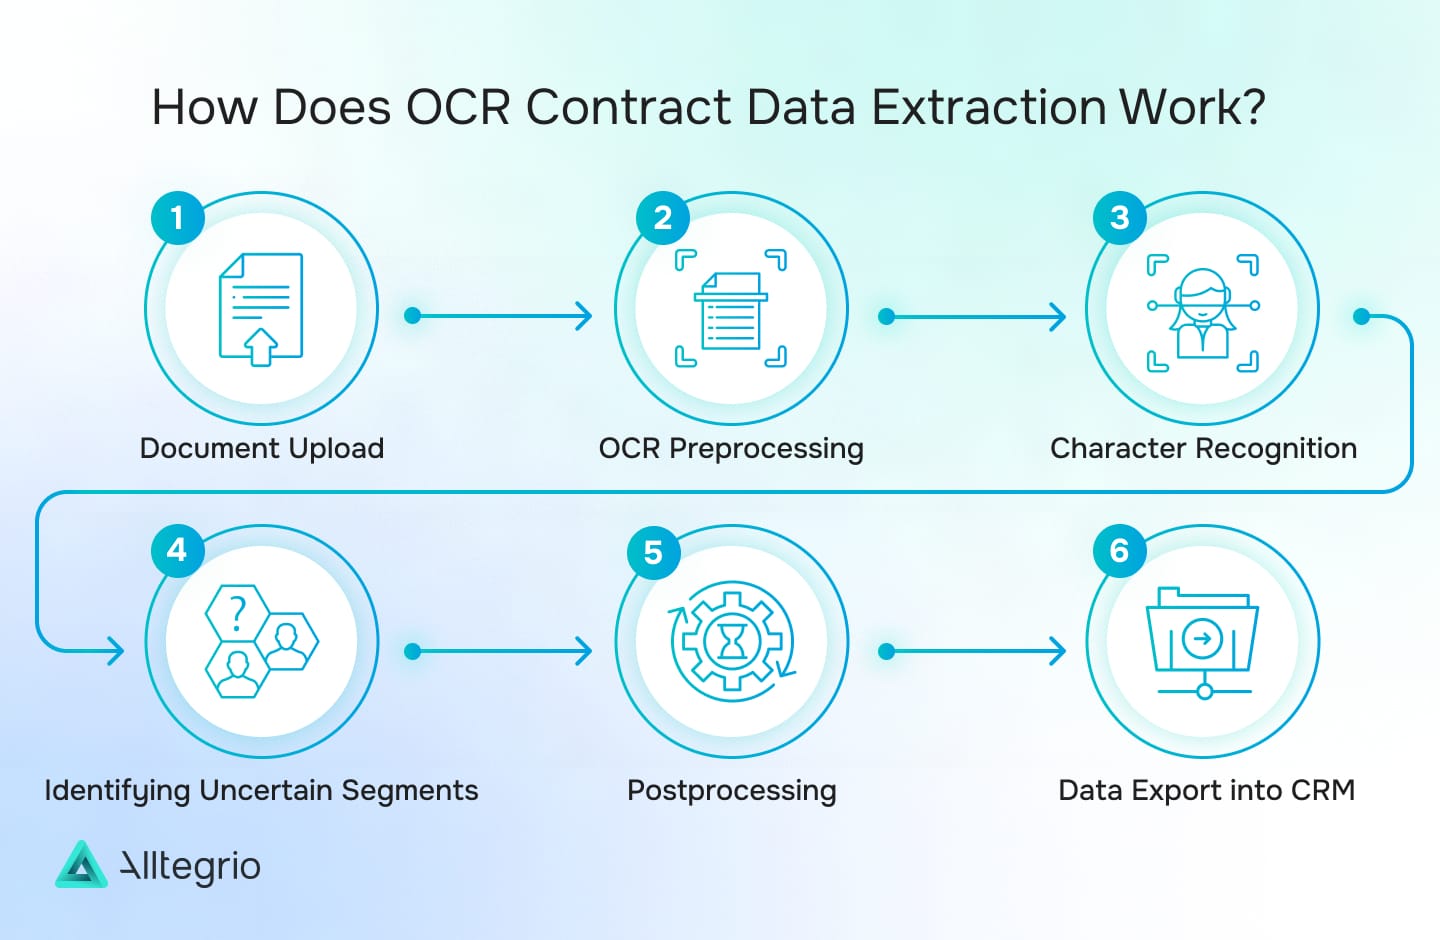
Basically, the AI OCR work process goes as follows:
- Image Acquisition
This is the step where the document enters the system: a scanner, a smartphone photo, an email attachment or a PDF from a supplier portal. Digital PDFs often already contain a text layer, which can be read directly and is more reliable than recognizing the image; scans and photos need recognition. Capture quality set here (resolution, lighting, angle) limits everything that follows, so mobile capture apps usually check sharpness and crop the page before upload. - Pre-Processing
The image is cleaned before recognition: noise reduction, skew and perspective correction (for photos taken at an angle), rotation detection, contrast adjustment and, for classic engines, binarization into black and white. Multi-page files are split and blank pages dropped. This helps most with faded paper documents, photos of crumpled delivery notes and pages with busy backgrounds. Vision-language models need less of it, but correcting rotation and cropping still improves their results. - Character Recognition
One of the most important aspects and key features of AI OCR is character recognition. This step relies on a Neural Network trained on very large collections of printed and handwritten text. Modern engines recognize whole lines and words in context rather than single characters, which is why they cope with unusual fonts and messy scans far better than older rule-based OCR. Vision-language models go one step further and combine recognition with understanding of the page layout. - Post-Processing
The recognized text is normalized: dictionary and context-based correction (a “0” inside a word becomes an “O”), dates and amounts converted to one format, decimal separators resolved by country, and reading order fixed for multi-column pages and tables. Errors that survive this step end up in business systems, so it matters most for fields such as amounts, account numbers and dates. - Field Extraction and Validation
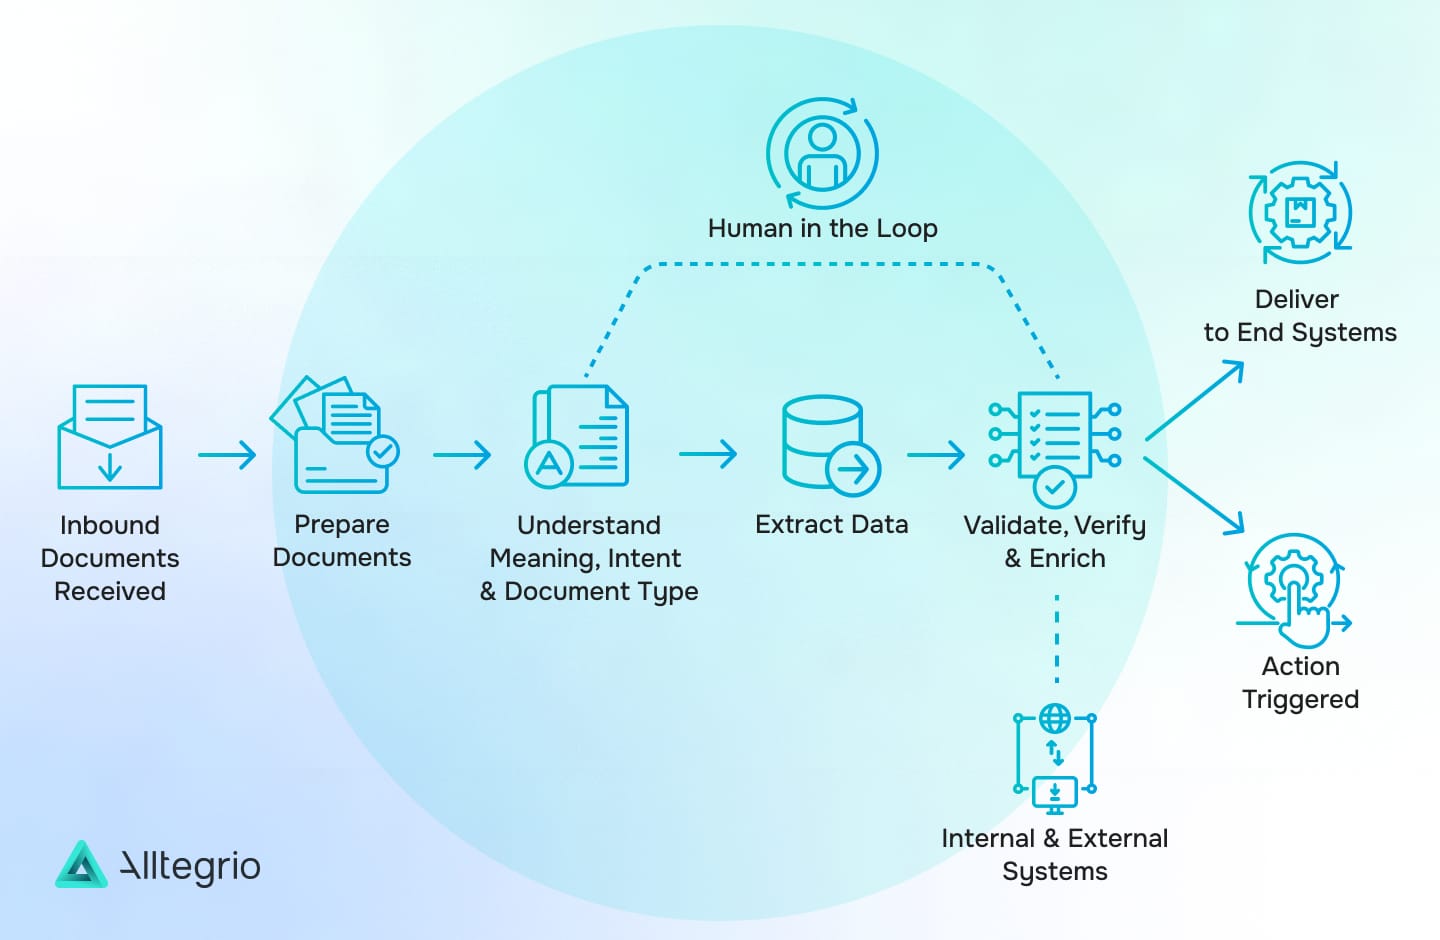
The system pulls the required fields from the recognized text, or directly from the image with a vision-language model, into a fixed structure such as JSON. Each field gets a confidence score, and code checks it against business rules: totals must match line items, dates must be valid, a supplier must exist in your records. - Human Review and Export
Fields with low confidence or failed checks go to a review queue where a person sees the value next to the highlighted spot on the original page and confirms or corrects it. Only then is the data exported to the ERP, TMS or accounting system. The corrections are kept and used to measure and improve accuracy over time.
What Are the Key Technologies Behind the AI OCR Algorithm?
AI OCR systems are built with Machine Learning development, and today they typically combine three layers:
- Text recognition engines, such as Tesseract, Google Cloud Vision or the read model in Azure AI Document Intelligence, which turn page images into text with positions on the page. They are fast and cheap per page.
- Document AI and vision-language models. Cloud document services ship prebuilt extractors for common documents: Amazon Textract’s AnalyzeExpense returns summary fields and line items from invoices and receipts without templates, and Azure’s prebuilt invoice model does the same within Document Intelligence. Multimodal language models understand layout, tables and handwriting and can return the fields you ask for as structured outputs that follow a JSON schema, even from document types they were not trained on.
- Validation and workflow code, which checks every field against business rules, routes uncertain fields to people, and writes approved data into business systems. This layer is what makes the output trustworthy.
These systems do not learn from mistakes on their own. Improvement comes from collecting the corrections people make in the review queue, measuring field-level accuracy on a fixed test set of real documents, and adjusting prompts, rules or models when a new document type or supplier format appears. Furthermore, combined with language models, AI OCR can understand textual data instead of just extracting it: it can classify documents, summarize contracts, and flag clauses that differ from a standard template.
Some of the most common applications of AI OCR include:
- Digitization of archives. Scanned contracts, records and historical documents become searchable. The output is full text with positions, and the main quality issue is old paper and unusual typefaces.
- Form processing. Applications, onboarding forms, claims and customs declarations are read into fixed fields. Checkboxes, handwriting and multi-page forms are the hard parts.
- Automated data entry from transactional documents. Invoices, receipts, bills of lading, proofs of delivery and packing lists feed accounting, ERP and transport systems. Accuracy on amounts, dates and reference numbers is what decides success.
The same capabilities serve healthcare (referral letters, insurance forms), finance (statements, KYC documents) and legal services (contracts, court filings), where document volumes are high and errors are costly. In each case the value is measured the same way: handling time per document, share of documents processed without a person touching them, and error rate on the fields that matter.
What Are the Key Challenges in AI OCR?
While AI OCR integration has many benefits, it also has a few challenges. Factors that could reduce the effectiveness of an OCR solution include:
- Image Quality
The lower the quality of an image, the lower the recognition rates. Blurriness, low contrast, and complex backgrounds make the situation worse. - Variable Text Layouts
Documents often have extremely versatile layouts and formats. This issue can make it challenging for the OCR system to identify the location and relations of texts precisely. - Language and Font Variations
Different languages or uncommon fonts might present a considerable challenge, especially if the OCR system is not well-trained for them.
Besides these main challenges, handwritten text remains harder than print. Handwriting can differ greatly from person to person, with unique styles, slants, and spacing. Vision-language models have made big progress here and read most legible handwriting on forms and delivery notes, but accuracy still drops on poor scans, unusual scripts and historical manuscripts. For handwritten fields, plan for a higher share of human review.
Another challenge specific to vision-language models is that they can hallucinate: return a plausible value that is not on the page, for example a total that “should” be there. This is why every extracted value should be traceable to a location on the original document and checked by rules in code before it is used.
Integrating OCR with various legacy system workflows might also be problematic. It’s very common to use legacy solutions in logistics as companies are used to their diverse arrays of hardware and software tools. Connecting them to a modern AI OCR service takes planning, but it is a well-understood job: here is how to integrate AI into legacy logistics systems.
Cost and speed are the last trade-off. Classic engines process a page in well under a second at a tiny cost, while a large vision-language model can take several seconds and cost far more per page, especially for long multi-page documents. Processing tens of thousands of pages a day in real time with the largest model is rarely necessary. The usual design routes documents by difficulty: known layouts go to a fast, cheap extractor, unfamiliar or messy ones to a stronger model, and anything that can wait is processed in batches. Check current per-page prices with each provider, since they change often.
What Are the Different Types of AI OCR Tools Available?
Modern enterprises can use various types of AI OCR tools depending on their specific needs. These can be classified into several broad types:
- Cloud-Based OCR Services
Platforms that offer OCR as a service and allow users to upload documents and have the results processed over the Internet. These are highly convenient and the major providers offer strong security controls, but documents leave your infrastructure, so check where data is processed and stored and whether the provider may use it for training. - On-Premises Solutions
Software installed on the organization’s servers or systems. These are popular due to the increased security and data privacy. - Mobile OCR Apps
Smartphone apps that are used for scanning and extracting text from documents via a camera phone while out of the office or on the go.
A fourth option sits between the first two: open-weight vision-language models run on your own servers or in a private cloud. They give document understanding close to the hosted models while keeping documents inside your infrastructure, at the cost of running GPUs and maintaining the model yourself. This is the usual choice when contracts or regulation do not allow documents to leave a specific region; see our notes on data residency.
| Deployment | Data location | Upfront effort | Running cost | Fits when |
|---|---|---|---|---|
| Cloud API | Provider’s region | Low | Per page | Volumes vary, data may leave your systems |
| On-premises engine | Your servers | Medium | Hardware and maintenance | Strict data rules, simple layouts |
| Self-hosted vision-language model | Your servers or private cloud | High | GPUs and maintenance | Strict data rules and varied documents |
| Mobile capture app | Device, then one of the above | Medium | Per user or per page | Field staff, drivers, inspectors |
AI-driven OCR tools can also be grouped by specialization. Some focus on handwriting, which helps with forms, notes and historical documents; even the best of them need more human review on difficult scripts. Others specialize in one document family, such as identity documents, bank statements or medical forms, with fields and validation rules built in.
Most current OCR solutions also go beyond text recognition. Combined with language models, they classify the document, extract meaning and connect it to other data. An invoice pipeline, for example, can extract line items, assign spend categories and match each invoice to its purchase order and goods receipt. Aggregated over months, that data shows spending patterns, price changes and how each supplier relationship develops.
How Can Enterprises Implement AI OCR Solutions?
| Service Type | Use Cases | Benefits |
|---|---|---|
| Automated Document Processing | Digitizing and categorizing documents, invoices, packing lists, etc. | Reduces manual data entry to the exceptions a person reviews, lowering the risk of errors and speeding up billing cycles. |
| Real-Time Shipment Tracking | Reading waybills and receipts on arrival at warehouses or distribution centers, alongside barcode scanners that read the package labels | Provides immediate visibility into shipment status, allowing for timely updates to customers and quicker issue resolution. |
| Streamlined Warehouse Management | Detecting whether delivery forms or contracts carry a signature or stamp where one is required | Flags missing signatures or stamps immediately; where authenticity matters, a person checks it. |
| Customs and Regulatory Compliance | Extracting details from shipping documents and customs forms for international shipments | Automates routine compliance checks, lowers the risk of fines due to incorrect documentation, and speeds up clearance. |
| Automated Billing and Invoicing | Parsing and processing invoice information from multiple suppliers and carriers | Increases efficiency in accounts payable/receivable workflows, enabling faster and more accurate payment processing. |
| Proof-of-Delivery (POD) Automation | Scanning and processing delivery confirmation receipts and driver manifests the moment they are signed | Reduces billing delays and disputes by providing immediate, verifiable proof of completed deliveries. |
| Route Optimization Assistance | Reading addresses and package labels instantly, feeding data into route-optimization algorithms | Minimizes travel time, reduces fuel costs, and improves on-time delivery rates by quickly and accurately parsing location details. |
| Image-Driven Quality Control | Reading and verifying product labels and barcodes in warehouse or loading areas, ensuring the right goods are shipped to the right place | Decreases shipping errors by automatically matching labels to orders and flagging inconsistencies immediately. |
| Predictive Analytics and Forecasting | Aggregating and analyzing data extracted via OCR from bills of lading, inventory logs, and order forms | Enables more accurate demand forecasting, capacity planning, and resource allocation in logistics operations. |
| Integrated Fraud Detection | Comparing shipping documents’ data (e.g., addresses, IDs, signatures) with trusted records to detect anomalies | Flags potential fraud or tampering quickly, providing an extra layer of security and compliance control. |
| Mobile Field Operations | Scanning delivery information with a mobile app for instant updates | Improves real-time data availability, ensuring operational visibility, even for remote or last-mile logistics. |
Implement AI OCR in Your Business
Learn how to implement OCR AI most effectively to cut costs and automate processes.
What Are the Best Practices for Using AI OCR Tools?
To get the most out of AI OCR tools, you should keep in mind the following:
- Ensure High-Quality Input
High-resolution images result in better recognition. A good scanner and proper lighting during image capture go a long way. - Measure Field-Level Accuracy
Build a test set of a few hundred real documents with checked values and measure accuracy for each field that matters. Re-run it after every model, prompt or software update, so an update never silently makes results worse. - Set Confidence Thresholds and a Review Queue
Decide per field how confident the system must be before a value is accepted automatically, and send everything else to a person. Money-related fields usually deserve the strictest thresholds. - Provide User Training
Reviewers need to know how the queue works, what each field means and when to escalate. Short, practical training reduces user errors. - Keep Every Value Traceable
Store, for each extracted field, the page and region it came from, the confidence score, the model or prompt version, and who confirmed or changed it. This makes audits possible and lets you find every document affected when a bug is discovered. - Protect the Documents
Invoices, IDs and contracts carry personal and commercial data. Encrypt documents in storage and transit, limit who can open the review queue, set retention periods, and confirm with each provider whether submitted documents may be used to train their models. - Pin and Test Model Versions
Hosted models are updated by their providers. Pin a version where possible and re-run your test set before switching.
Review the output regularly as well. Recurring errors, such as one supplier’s layout or one field that is often wrong, show the development team which prompts, rules or settings to adjust.
This loop steadily improves the reliability of the extracted data. Track two numbers over time: the share of documents that pass straight through without human review, and the error rate on fields after review. The first shows efficiency; the second shows whether efficiency is being bought with mistakes.
What Are the Future Trends in AI OCR?
AI OCR keeps developing. The trends worth watching are:
- Integration with AI Agents
AI OCR is becoming one step inside AI agents that handle a whole process: an agent receives an invoice by email, extracts it, matches it to the purchase order and delivery note, and prepares the payment for a person to approve. This replaces much of the screen-based RPA used for the same job a few years ago. - Multilingual Support
Vision-language models already read many languages and scripts without separate training, which makes these solutions more versatile for businesses that operate globally. The remaining work is testing accuracy on your own documents in each language. - Real-Time Data Processing
With faster and cheaper models, AI OCR can process documents the moment they arrive, for example at a warehouse gate or a customs checkpoint, instead of in nightly batches.
Cloud computing also matters. With cloud infrastructure, organizations can use AI OCR without investing in on-premise hardware, pay for the volume they process and scale up for peaks. Updates are easier to roll out in the cloud, though each one should be tested against your own documents first.
Security and data privacy get more attention too. Documents carry personal and commercial data, so encryption, access controls and clear data-retention rules are essential, along with compliance with regulations such as the GDPR, and with sector rules such as HIPAA where US health data is involved. Before choosing a tool, buyers in healthcare, finance and the legal sector should get written answers on where documents are processed, whether they are used for model training, and how long they are kept.
Please note that if you plan to use fast-developing AI OCR solutions as an investment opportunity, you should invest in comprehensive technical due diligence first.
When Should Businesses Start Implementing AI OCR?
The simple answer is: as soon as your team spends a noticeable share of its time typing data from documents into systems. Document processing is one of the AI projects with the clearest return, because the current cost of manual entry is easy to measure and the results can be checked field by field.
Start with one document type that comes in high volume, such as supplier invoices or proofs of delivery, measure the current handling time and error rate, and run a pilot with a review queue. There are quite a few ways to use AI in supply chain management. AI OCR is one of the most practical starting points for process automation, and it often becomes the first building block for AI agents that run whole back-office processes.
If you want to understand how to make the most of this technology, book a free consultation by filling out the form below.